Does Replicate Work in China? Prompts, Outputs, the Generative-AI Filing & Cross-Border Data
Replicate runs and hosts open ML models through an offshore API with no mainland-China region, so every prompt, image, audio clip, document and output you send is a PIPL cross-border transfer — and a public mainland generative-AI feature needs a CAC filing. A compliance-first look at residency, the filing gate, and the lawful China path.
Does Replicate work in China?
Reachable or not, the deciding question is legal: every prompt, image, audio clip, document and generated output you send to Replicate leaves the mainland for offshore infrastructure, and a public China-facing generative-AI feature you build on it needs a CAC filing.
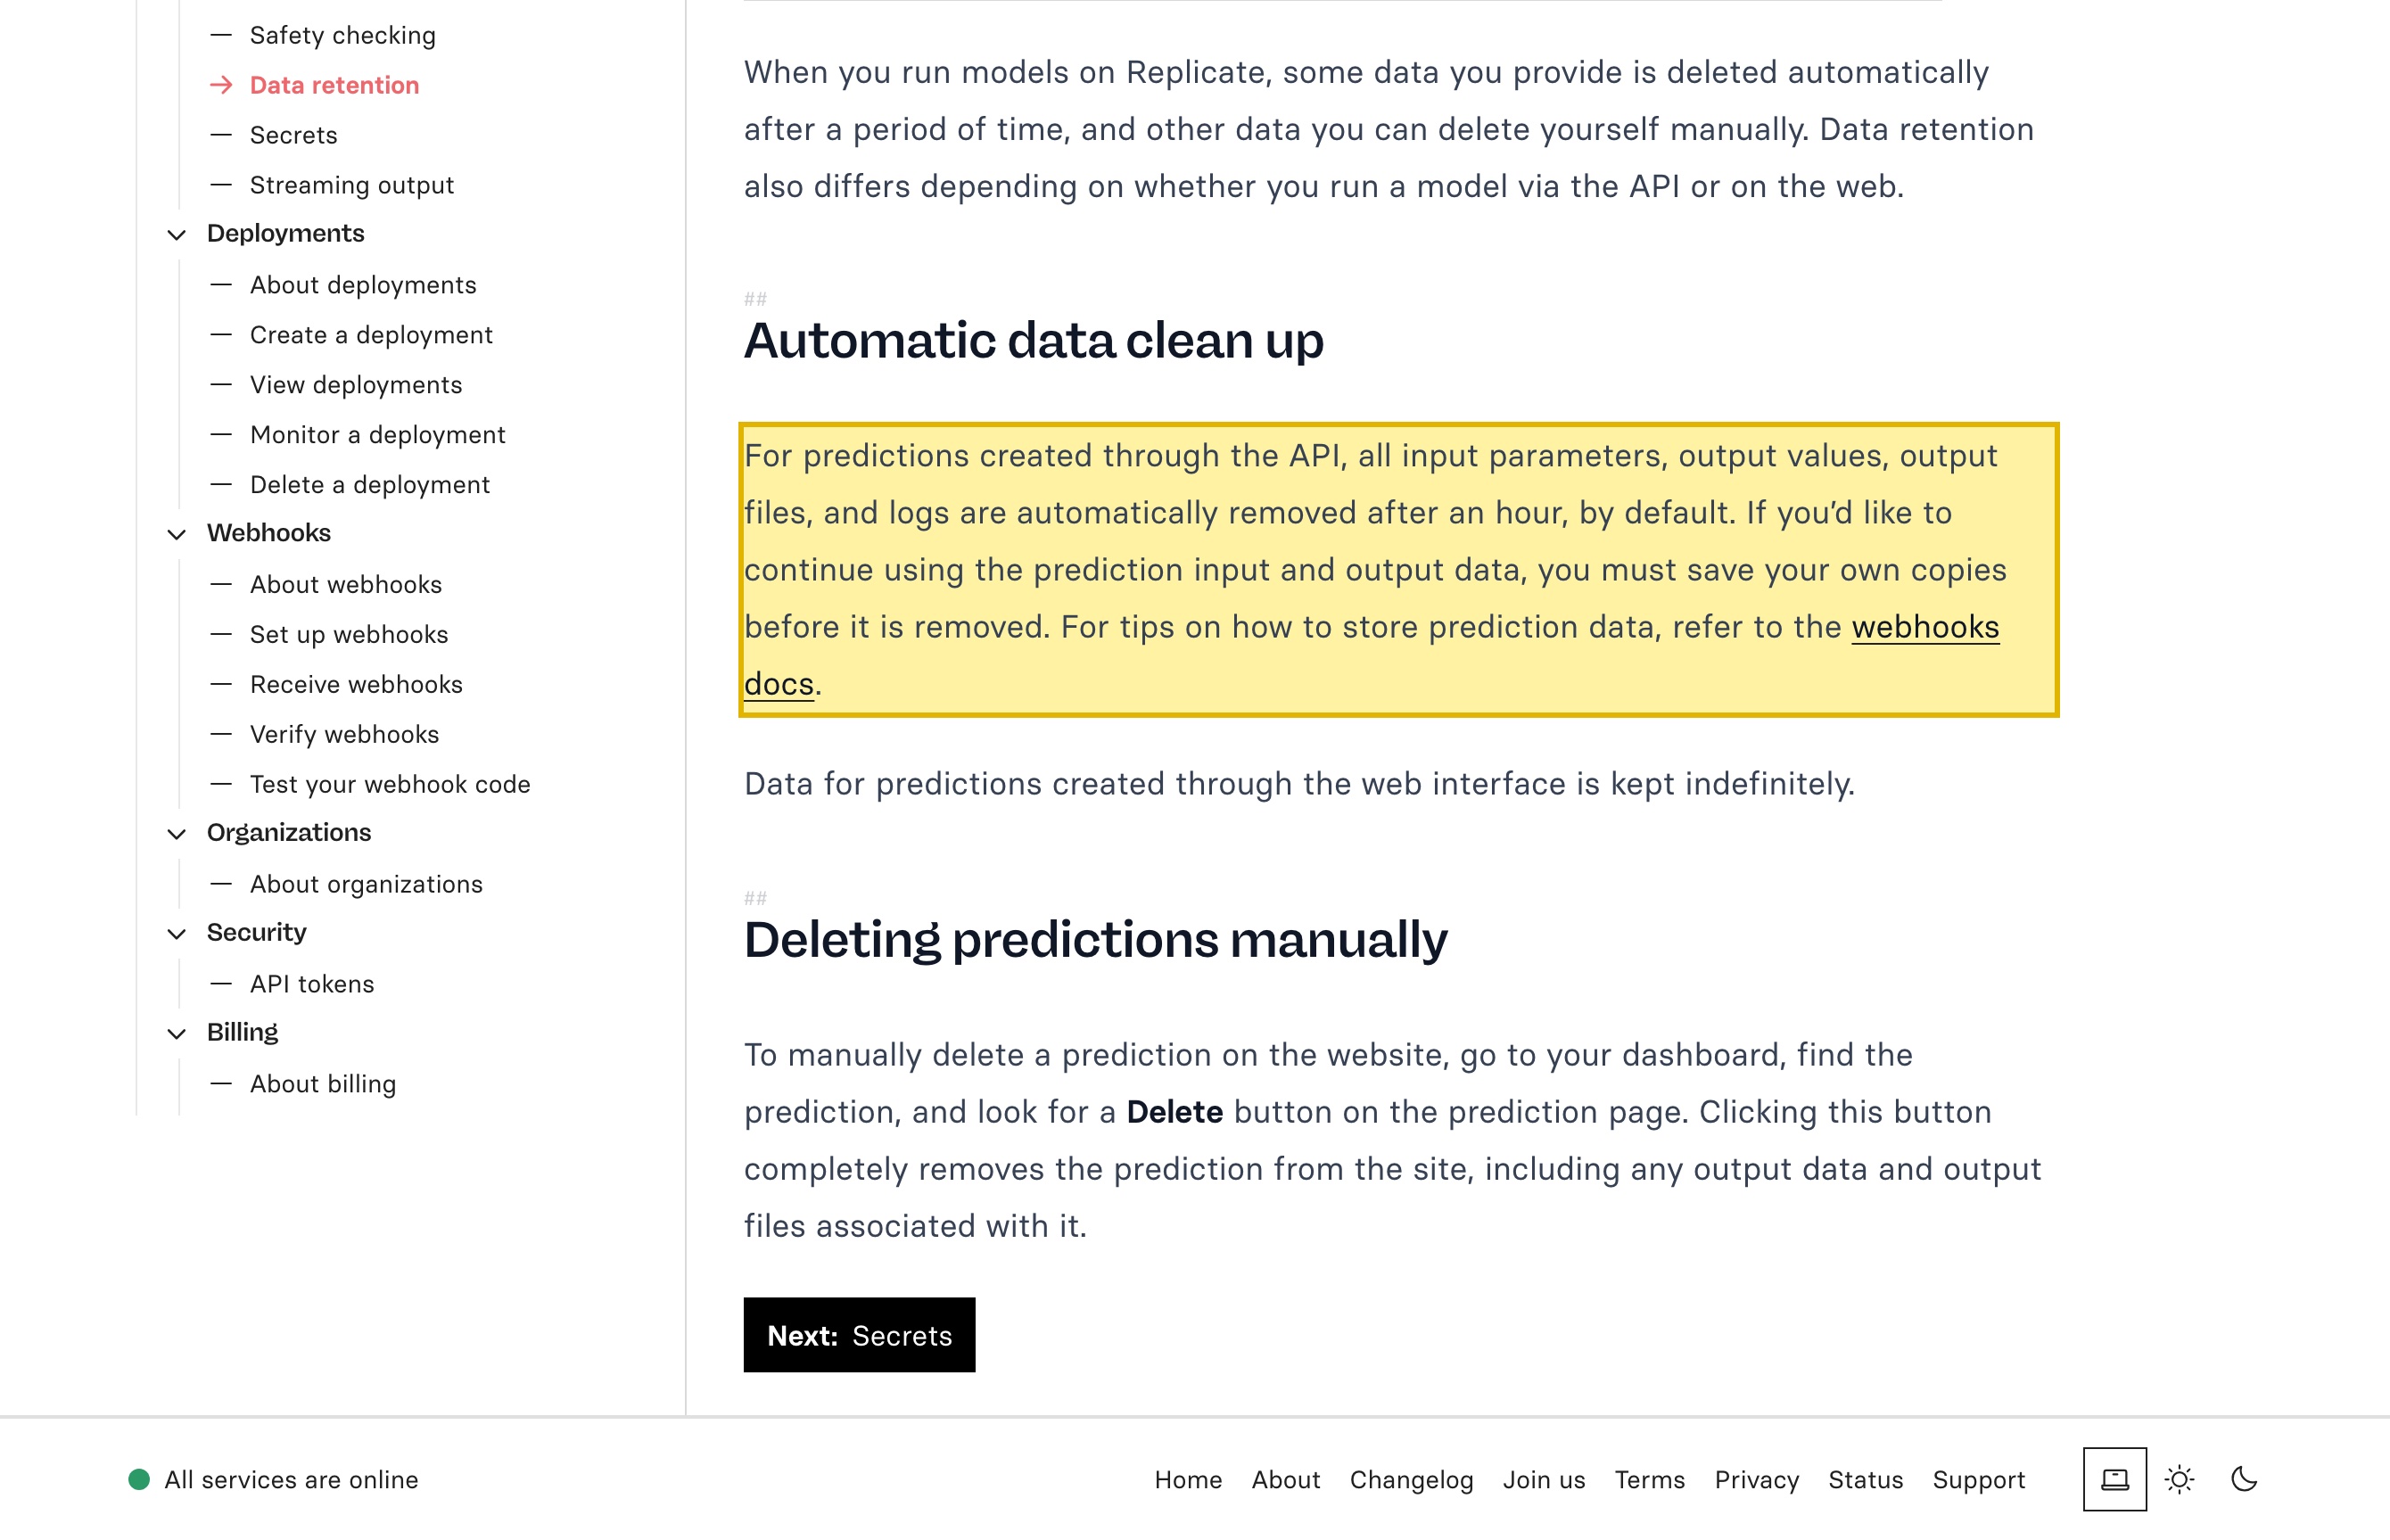
Replicate runs no mainland-China region — its own docs say API inputs, outputs and logs are “automatically removed after an hour, by default,” while web-interface runs are “kept indefinitely,” all on offshore infrastructure (now Cloudflare’s, after the 2025 acquisition). Sending prompts, reference images, fine-tuning data or source code there is a PIPL cross-border transfer (Articles 38–40), and these inputs routinely carry personal information, trade secrets, and sometimes sensitive data (Article 28). Separately, offering a public generative-AI feature to mainland users turns on the Interim Measures for the Management of Generative AI Services filing and AI-content labeling — a duty on you, not on Replicate.
This is a risk map, not a ruling — settle the specifics with qualified counsel. Our China team can map your exposure →
What Replicate's own documentation says about China
| Fact | Primary source |
|---|---|
| Replicate keeps your run data on offshore infrastructure — briefly for the API, indefinitely for the web. Its data-retention docs state that for API predictions “all input parameters, output values, output files, and logs are automatically removed after an hour, by default,” while “Data for predictions created through the web interface is kept indefinitely.” Either way, your inputs and the generated outputs are processed and stored outside mainland China. | Replicate Docs — Data retention (retrieved 2026-10-10) |
| Replicate is a US-governed service with no mainland-China region or entity. Its Terms of Service are “governed by the Laws of the State of California,” with disputes heard in San Francisco, and its privacy policy casts Replicate as a “processor” under U.S. state privacy law. In late 2025 Cloudflare announced its acquisition of Replicate; the service continues under the Replicate brand on offshore infrastructure, with no mainland-China region to select. | Replicate Terms of Service & Privacy Policy (retrieved 2026-10-10) |
| Sending prompts, fine-tuning data or source code to an offshore model is a cross-border transfer of personal information. Under PIPL Articles 38–40, the handler must give notice, obtain a separate consent, and use a transfer mechanism — a CAC security assessment, the CAC standard contract, or certification. Where a prompt carries faces, IDs, financial, health or minors’ data, PIPL Article 28 sensitive-PI rules add further duties. | Personal Information Protection Law (PIPL), Articles 28 and 38–40 |
| A public mainland generative-AI feature needs a CAC filing — and you file it, not Replicate. China’s Interim Measures for the Management of Generative AI Services (生成式人工智能服务管理暂行办法, CAC, effective August 15, 2023) govern offering generated text, images, audio or video to the public in China — algorithm filing and content-safety duties — and China’s 2025 rules on labeling AI-generated content add conspicuous labels. The obligation attaches to the operator who serves the feature. | Interim Measures for the Management of Generative AI Services (CAC, effective 2023-08-15) |
Sources verified by the 21YunBox compliance team on 2026-10-10.
For a product aimed at mainland China, the first question about Replicate is not whether the API answers — it almost always will. It is whether the data you hand it may lawfully leave the country, and whether the feature you build on top of it needs a Chinese regulator’s sign-off. Replicate runs and hosts open machine-learning models — image, video, audio and language — behind an offshore API, with no mainland-China region to select. Everything you send it is content: prompts, reference images, audio clips, documents and retrieved context for RAG, fine-tuning data, and the source packaged into a model’s Cog container — plus the images, video, audio and text it generates back. That payload routinely carries personal information, and often trade secrets and credentials. In late 2025 Cloudflare announced its acquisition of Replicate; the service continues under the Replicate name, still on offshore infrastructure. So the decision is a compliance one, and it has two doors.
Replicate in China at a glance
| What decides it | In Replicate's own terms — and China's law |
|---|---|
| Where inference runs | Offshore, with no mainland-China region to select. Replicate's Terms of Service are “governed by the Laws of the State of California”; since Cloudflare's 2025 acquisition the hosted service runs on Cloudflare's global network — a worldwide edge, not a CAC-filed Chinese inference region. |
| What you send it | Prompts, reference images, audio, documents and RAG context, fine-tuning datasets, and the source in a model's Cog container — plus the generated outputs. This is personal information, and often trade secrets and credentials; faces, government IDs, financial, health or minors' data make it sensitive personal information under PIPL Article 28. |
| Your users' prompts and your code | Every call carries that payload out of the mainland to an offshore model, so it is a cross-border transfer of personal information under PIPL (Articles 38–40): notice, a separate consent, and one transfer mechanism. Replicate's docs show API inputs, outputs and logs are kept about an hour by default; web-console runs are kept indefinitely. |
| A public mainland gen-AI feature | Offering generated text, images, audio or video to the public in China turns on the Interim Measures for the Management of Generative AI Services (生成式人工智能服务管理暂行办法, CAC, effective Aug 15, 2023) — algorithm filing and content-safety duties, plus AI-content labeling under the 2025 rules. The duty is the operator's — yours — not Replicate's. |
| The deciding axis | Not whether the endpoint responds, but whether the data may lawfully leave China and whether your public feature is filed. The China-facing surface that carries it — the app, the chat UI, the API edge your users hit — also carries an ICP filing (备案) duty. |
No mainland region, so your prompts, images and data leave the country
Replicate does not offer a mainland-China region, and nothing in its documentation lets you pin inference to Chinese soil. Its Terms of Service are “governed by the Laws of the State of California,” with disputes heard in San Francisco; its privacy policy describes Replicate as a “processor” under U.S. state privacy law. Since Cloudflare’s 2025 acquisition the hosted service is slated to run on Cloudflare’s global network — a worldwide edge, not a CAC-filed Chinese inference region. Whichever way you reach it, the model runs outside the mainland.
That matters because the data does not merely pass through. Replicate’s own data-retention documentation states that for predictions created through the API, “all input parameters, output values, output files, and logs are automatically removed after an hour, by default,” and that “Data for predictions created through the web interface is kept indefinitely.” In other words, your inputs and the generated outputs are processed and stored on offshore infrastructure — briefly for the API, indefinitely for the web console — before any retention choice of your own applies. Reaching the endpoint was never the hard part; keeping the data on a lawful footing is.
What you send it is personal information
It is easy to picture a model call as anonymous text, but look at what actually crosses the border. Prompts and chat turns contain names, contact details, order and account numbers, and whatever a user pastes in. Reference images and video carry faces; audio carries voiceprints; uploaded documents and RAG corpora carry customer records and internal material. Fine-tuning datasets are, by construction, a concentrated export of exactly the data you most want to keep. And for teams wiring Replicate into a build pipeline, the source and configuration packaged into a Cog container can carry secrets, credentials and proprietary logic. All of this is personal information — and often trade secrets — the moment it leaves China for an offshore model.
Where that payload includes faces, government IDs, financial or health data, or anything about minors, it is sensitive personal information under PIPL Article 28, which raises the bar again: a specific purpose, strict necessity, and a heightened, separate consent. We found no Replicate statement that it trains its own models on your inputs — the exposure here is not a training-use default but the transfer itself and how long the data sits offshore (indefinitely for web-console runs, by Replicate’s own docs). Trimming what you send helps; it does not change the fact that it left the country.
The filing gate — and why trimming retention doesn’t close the door
Suppose you solve the engineering and put a “generate” button, an assistant, or a voice feature in front of users in the mainland. A second gate opens that has nothing to do with Replicate’s uptime. Offering a public-facing generative-AI service inside China turns on the Interim Measures for the Management of Generative AI Services (生成式人工智能服务管理暂行办法, Cyberspace Administration of China, effective August 15, 2023): obligations on training data and content safety, an algorithm filing for services able to shape public opinion, and — under China’s 2025 rules on labeling AI-generated content, in force September 1, 2025 — conspicuous labels on generated images, video, audio and text. If your feature ranks or recommends what it serves, the Algorithm Recommendation Provisions filing can apply as well. These duties attach to the operator who serves the feature to the Chinese public — you — not to the upstream API vendor, which files none of this on your behalf. The China-facing surface that carries it — the app, the chat window, the API edge your mainland users hit — also carries an ICP filing (备案) duty.
This is why a zero-retention setting or Replicate’s one-hour API default does not close the door. Those controls reduce what crosses and how long it lingers; they do not change that it crossed. The cross-border transfer under PIPL and the generative-AI filing duty are unaffected by a shorter retention window. Where personal information or important data must stay in China — for a critical-information-infrastructure operator — Cybersecurity Law Article 39 (formerly Article 37) imposes a data-localization duty that an offshore model cannot satisfy; the 2025 Cybersecurity Law amendment, in force January 1, 2026, renumbered the data-localization article from 37 to 39, with the substance unchanged. None of this is a ruling on your specific build: treat it as a map of exposure, and settle the specifics with qualified Chinese counsel against what you actually ship.
The lawful path — map, localize, deliver
There is a lawful way to put Replicate-style model output in front of users in China, and it does not rely on anything unlawful. Because Replicate hosts open models packaged as Cog containers, you are rarely locked to one offshore endpoint — and that is the opening. 21YunBox’s China team does three things. We map your exposure: the PIPL cross-border and sensitive-PI position, the generative-AI filing and labeling duties, and the ICP obligation, read against your entity, your data volumes, and who your users are. We localize the model call that cannot lawfully be served offshore — standing up and integrating a CAC-filed domestic model or an in-China sovereign-cloud model, or self-hosting the same open model in-country where its license allows, so the generation your mainland users trigger happens on lawful Chinese infrastructure. And we deliver the China-facing surface — the app, the chat UI, the API edge — over ICP-filed, in-country infrastructure (the 21YunBox Optimizer), in front of the stack you already run, with no rebuild and no second codebase.
The distinction is the whole point: localize means a China-legal model, not a route to the offshore one. 21YunBox never uses or suggests circumvention of any kind. The result is an AI feature that runs legally and compliantly for your users in China — a compliant overlay on the stack you have, not a migration, and a partner to Replicate, not a competitor.
Related reading:
- China’s Interim Measures for the Management of Generative AI Services
- Cross-border data transfers under PIPL
- How to get an ICP filing for China
- China’s Cybersecurity Law — data localization (Article 39)


