Does Cursor Work in China? Code Residency, Repo Indexes & Cross-Border Data
Cursor is reachable and usable in mainland China — but it runs no in-country region, so your source code, repository index, prompts, and context are sent to US servers and offshore models. That makes it a PIPL cross-border transfer of trade secrets and personal data. A compliance-first look at code residency, Privacy Mode, and the filing gate.
Does Cursor work in China?
Cursor is reachable and usable in mainland China — so the honest answer is not a block; it is code residency. Cursor runs no infrastructure in China, so a developer in the mainland reaches it across the border: your source code, the repository index and embeddings it builds, your prompts, and your editor context are sent to Cursor's US servers and fan out to offshore frontier models (OpenAI, Anthropic, and others).
That code almost always carries trade secrets, and often embedded credentials and personal information in comments, fixtures, and logs — so sending it offshore is a PIPL cross-border transfer (Articles 38–40, and Article 28 where the data is sensitive). Privacy Mode and zero-data-retention agreements reduce what is kept and stop training, but not the fact that the code crosses the border. The generative-AI filing gate is lighter here — Cursor is a developer tool, not a public service to the mainland public — but a public mainland generative feature you build with it would need its own filing.
This is a risk map, not a ruling — settle the specifics with counsel. Our China team can map your exposure →
What Cursor's own documentation says about China
| Fact | Primary source |
|---|---|
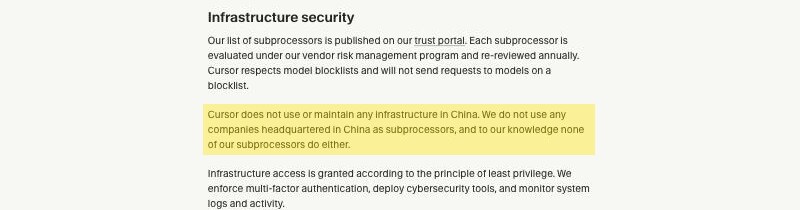
| Cursor operates no infrastructure in China; your code runs on its US servers. Cursor's security page states: “Cursor does not use or maintain any infrastructure in China. We do not use any companies headquartered in China as subprocessors.” Its privacy policy places personal data on servers “located in various jurisdictions, including in the United States.” There is no mainland-China region to select, so a developer in China reaches Cursor across the border. | Cursor Security page and Privacy Policy (cursor.com), retrieved 2026-10-10 |
| With Privacy Mode on, your code still crosses to offshore models — it just is not retained or used for training. Cursor's Data Use & Privacy Overview says it “maintains zero data retention (ZDR) agreements with all providers, and AI model providers will not store or train on your data,” while noting abuse detectors may still store flagged prompts. With Privacy Mode off, Cursor “may use and store codebase data, prompts, editor actions, code snippets, and other code data and actions to improve our AI features.” Either way the code reaches offshore inference (OpenAI, Anthropic, and others). | Cursor Data Use & Privacy Overview (cursor.com/data-use), retrieved 2026-10-10 |
| Sending a China developer's code offshore is a PIPL cross-border transfer. Where that code or context carries personal information — names, credentials, or customer records in comments, fixtures, or logs — China's Personal Information Protection Law requires notice, a separate consent, and one transfer mechanism (a CAC security assessment, the CAC standard contract, or certification) under Articles 38–40, with Article 28 adding duties where the data is sensitive. | Personal Information Protection Law of the PRC, Articles 28 and 38–40 (cac.gov.cn), retrieved 2026-10-10 |
| The CAC generative-AI filing gate targets the public feature you ship, not the editor. China's Interim Measures for the Management of Generative AI Services (CAC Order No. 15) apply to generating content “to the public” within China (Article 2). Cursor used by your own engineers is not that; but a public mainland generative feature you build with it turns on the filing, content-safety, and AI-content-labeling duties. | Interim Measures for the Management of Generative AI Services, CAC Order No. 15, Art. 2 (cac.gov.cn), retrieved 2026-10-10 |
Sources verified by the 21YunBox compliance team on 2026-10-10.
For a mainland-China audience, the first thing to settle about Cursor is that the question is not whether it loads. Cursor — the AI code editor built by Anysphere — is reachable and usable from the mainland; it is a developer tool, not a consumer service that gets blocked. What actually decides the matter is residency: to index your repository, complete code, and run agents, Cursor sends your source code, the repository index and embeddings it builds, your prompts, and the surrounding editor context to its own servers and on to offshore frontier models. Cursor runs no infrastructure in China — by its own statement — and hosts in the United States, so every one of those requests leaves the country. Source code is rarely just logic: it carries trade secrets, and routinely embedded credentials, API keys, and personal information in comments, fixtures, and test data. Moving it offshore is the compliance event, not the round-trip time.
Cursor in China at a glance
| What decides it | In Cursor's own terms — and China's law |
|---|---|
| Where it actually runs | Cursor is a standalone AI editor built by Anysphere. Its security page states plainly: "Cursor does not use or maintain any infrastructure in China." Its privacy policy places personal data on servers "located in various jurisdictions, including in the United States." Requests fan out from there to offshore frontier models (OpenAI, Anthropic, and others) and Cursor's own models. There is no mainland-China region to select. |
| What you send it, and why it is personal information | To complete and reason over your project, Cursor sends your source code, the repository index and embeddings it builds, your prompts, and the surrounding editor context. That code routinely embeds credentials, API keys, customer records in test data, and names in comments — personal information, and sensitive personal information under PIPL Article 28 where IDs, financial, or health data appear. It is also, almost always, trade secrets. |
| Your China developers' code crossing the border | When a developer in the mainland triggers a completion, a chat, or an agent, that code and context leave the country to Cursor's offshore service. Under the Personal Information Protection Law that is a cross-border transfer (Articles 38–40): notice, a separate consent, and one transfer mechanism — a CAC security assessment, the CAC standard contract, or certification. |
| Does the generative-AI filing gate apply? | To the editor itself, generally no. The CAC Interim Measures for the Management of Generative AI Services govern services that generate content "to the public" within China (Article 2); an internal coding tool used by your own engineers is not that. The gate turns on only if you ship a public-facing generative feature to users in the mainland — a separate, downstream filing question. |
| Reachability is not the axis | Cursor is reachable and usable from the mainland, so this is not a block and speed is not the deciding factor. The decision turns on residency — whether your code may lawfully leave the country. Any China-facing surface your team then ships still carries an ICP filing (备案) duty and needs compliant, in-country delivery. This page publishes no first-party latency figure; speed is the wrong axis. |
No mainland region, so your code and its index leave the country
Start with where Cursor runs, because that is what the whole question rests on. Cursor’s security page is unusually direct: “Cursor does not use or maintain any infrastructure in China. We do not use any companies headquartered in China as subprocessors, and to our knowledge none of our subprocessors do either.” Its privacy policy places personal data on servers “located in various jurisdictions, including in the United States.” There is no in-country Cursor region, so a developer sitting in Shanghai or Shenzhen reaches a US-hosted service across the border every time the editor does anything intelligent.
What makes Cursor a sharper residency question than a plain in-IDE completion plugin is how much it sends. Cursor is an agentic editor: it indexes your whole repository, building an index and embeddings so its models can retrieve across files, and it passes your prompts, edits, and surrounding context to frontier models it operates offshore and to upstream providers such as OpenAI and Anthropic. So the data that crosses the border is not a few lines around the cursor — it is a representation of the codebase itself, plus the stream of prompts and context your engineers generate as they work. None of that turns on how fast a suggestion streams back. It turns on whether a representation of your source code had a lawful basis to leave the mainland in the first place.
What you send it is personal information — and usually trade secrets
A codebase is not neutral text. It carries comments, configuration, fixtures, logs, and test data, and those routinely embed names, contact details, credentials, API keys, and real customer records. The moment a developer in China sends that to a model hosted outside the mainland, it is a cross-border transfer of personal information under China’s Personal Information Protection Law. PIPL puts the duty on the handler — you: Articles 38–40 require notice, a separate consent, and one transfer mechanism (a CAC security assessment, the CAC standard contract, or certification), and Article 28 adds heightened duties where the data is sensitive — government IDs, financial, health, biometric, or minors’ information that so often lurks in seed data and tickets.
Before it is a compliance question it is a confidentiality one: a representation of your proprietary source code — and the trade secrets inside it — leaving the country. Your corporate data-governance policy decides which repositories, files, and secrets may go anywhere near an offshore assistant, and Cursor’s own defaults matter here. With Privacy Mode turned off, Cursor’s data-use overview says it “may use and store codebase data, prompts, editor actions, code snippets, and other code data and actions to improve our AI features”; with Privacy Mode on, it commits not to train on your data. Either setting still sends the code offshore to produce a result. And if any of that code or data is “important data,” or your organization operates critical information infrastructure, the Cybersecurity Law adds a data-localization duty — Article 39 (as renumbered by the 2025 amendment in force January 1, 2026; the rule formerly numbered Article 37, substance unchanged) requires personal information and important data collected and generated in-country by such operators to be stored in-country, with a security assessment before any export.
Privacy Mode reduces what is retained, not that your code crosses the border
It is tempting to treat Privacy Mode and “zero data retention” as the compliance answer. They are real and worth having — but they solve a different problem than residency. In Cursor’s own words, with Privacy Mode on it “maintains zero data retention (ZDR) agreements with all providers, and AI model providers will not store or train on your data.” Read closely, that governs what is kept and whether it trains a model after the data arrives — not whether the data arrives offshore in the first place. The code still crosses the border to produce a completion. Cursor itself notes the edges: abuse detectors may still store flagged prompts for investigation, non-ZDR models have to be opted into, and bringing your own API key moves requests outside those protections and under the provider’s own policy. Trimming retention narrows the blast radius; it does not change the residency fact, and it does not touch any filing duty.
On that filing gate, the honest answer here is lighter than for a consumer AI service — and it is worth being plain about it. China’s Interim Measures for the Management of Generative AI Services (生成式人工智能服务管理暂行办法, CAC Order No. 15) apply to using generative AI “to provide services for generating text, images, audio, video, and other content to the public within the territory of the People’s Republic of China” (Article 2). Cursor used by your own engineers inside their editor is not a public content service, so the filing that gates a mainland consumer chatbot generally does not apply to the tool. The caveat is about what you build with it: take a model-powered feature to the Chinese public and that downstream service is a different thing, needing its own filing, content-safety measures, and AI-content labeling — and, where it ranks or recommends, the Algorithm Recommendation Provisions as well. Any China-facing surface you ship also carries an ICP filing (备案) duty. This page maps exposure; it does not rule on your facts — settle the specifics with your counsel against the real product and data you handle.
The lawful path — map, localize, deliver
For a developer tool, 21YunBox’s role is lighter than it is for a consumer AI feature, and we will say so plainly: there is no “domestic Cursor,” and we are not a way to localize Cursor itself — that editor is Anysphere’s, operated offshore. Our value is in three moves.
First, we map the exposure: what your developers actually send offshore — source code, the repository index, prompts, context — whether any of it is personal, sensitive, or “important data,” and how that lands against PIPL’s cross-border rules, Article 28, the Cybersecurity Law, and your own code-governance policy, so you and your counsel can set the guardrails (which repositories are in scope, what must never leave, what consent and records are required). Second, we help you localize the part that cannot lawfully be served offshore: stand up a lawful China-legal coding path where one exists — a self-hosted or on-premise model, or a CAC-filed domestic large model integrated in place of the offshore call — and keep consented, in-country processing and storage for what must stay on mainland soil. This is a China-legal alternative, never a route to the offshore model. Third, we deliver any China-facing surface your team ships — the app, the internal portal, the API edge your mainland users hit — over ICP-filed, in-country infrastructure (the 21YunBox Optimizer), in front of the stack you already run, with no rebuild and no second codebase.
21YunBox is a compliant overlay, not a migration, and a partner to the tools you use, not a competitor to them. 21YunBox never uses or suggests circumvention of any kind. The result is a setup that runs legally and compliantly for your users in China.
Related reading:
- China’s Interim Measures for Generative AI Services
- Cross-border data transfers under PIPL
- How to get an ICP filing for China
- China’s Cybersecurity Law (data localization, Article 39)


